Cybersecurity Incident Response Timeline 2026: From Detection to Recovery
A cybersecurity incident response timeline shows how an organization moves from the first sign of suspicious activity to containment, recovery, and post-incident improvement.
The timeline matters because cyber incidents do not wait for teams to organize themselves.
A compromised credential can be reused within minutes. Malware can spread laterally. Cloud tokens can be abused. Data can be copied before the security team fully understands what happened.
The faster an organization can:
detect → validate → contain → investigate → recover
the less opportunity an attacker has to expand the incident.
But speed alone is not enough.
Fast decisions must also be:
- coordinated;
- evidence-based;
- documented;
- reversible where possible;
- aligned with business and regulatory obligations.
NIST’s current incident-response guidance, SP 800-61 Rev. 3, says incident response should be integrated throughout cybersecurity risk management rather than treated as an isolated technical process. Rev. 3 is aligned with the six functions of the NIST Cybersecurity Framework 2.0 and supersedes the older Rev. 2 guide.
The practical objective is therefore not simply:
“Close the alert quickly.”
It is:
“Understand the incident quickly enough to contain damage, make sound business decisions, meet reporting obligations, and restore operations safely.”
Incident Response Timeline at a Glance
| Phase | Primary objective | Example actions |
|---|---|---|
| Preparation | Be ready before an incident | Playbooks, roles, logging, backups |
| Detection & validation | Determine whether an incident is real | SIEM/EDR review, evidence collection |
| Containment | Stop further damage | Isolate hosts, revoke sessions |
| Investigation & eradication | Remove attacker access and root cause | Remove persistence, patch vulnerabilities |
| Recovery | Restore trusted operations | Restore systems, validate backups |
| Post-incident improvement | Reduce recurrence | Root cause, lessons learned, metrics |
This is a practical operating model. NIST Rev. 3 does not mandate that every organization use exactly six numbered phases.
Table of Contents
What Is a Cybersecurity Incident Response Timeline?
A cybersecurity incident response timeline is a chronological view of:
- what happened;
- when it was detected;
- how the organization responded;
- when the threat was contained;
- when recovery began;
- when normal operations resumed.
A strong timeline also records important decision points such as:
- incident severity classification;
- legal escalation;
- regulatory trigger assessment;
- customer notification;
- executive approval;
- recovery authorization.
That makes the timeline useful not only to SOC and incident-response teams, but also to:
- legal;
- compliance;
- privacy;
- business leadership;
- board members;
- insurers;
- regulators.
For a more detailed chronology format, use the Data Breach Timeline Template.
Why Incident Response Speed Matters
Slow response gives attackers more time to:
- steal credentials;
- escalate privileges;
- move laterally;
- exfiltrate data;
- deploy ransomware;
- create persistence;
- disrupt business operations.
However, the goal should not simply be “respond faster.”
The stronger goal is:
reduce the time between reliable decision points.
That includes:
- time to detect;
- time to validate;
- time to escalate;
- time to contain;
- time to eradicate;
- time to recover.
NIST says integrating incident response into cybersecurity risk management can reduce the number and impact of incidents and improve the efficiency of detection, response, and recovery activities.
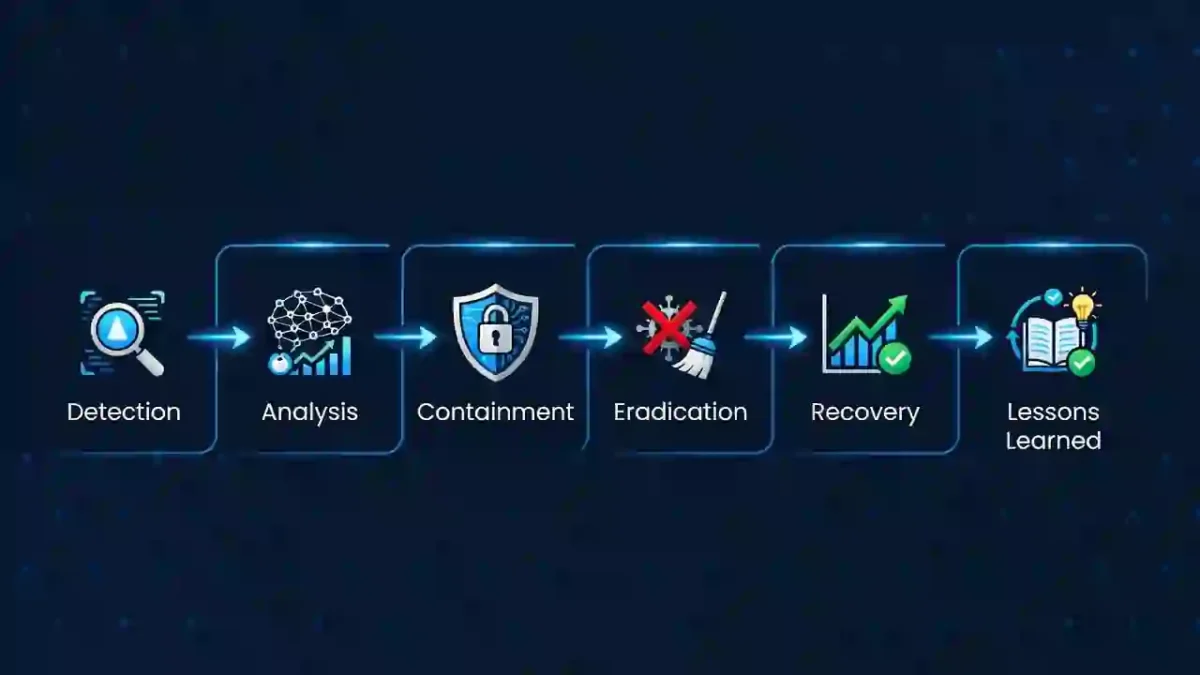
Most organizations follow the NIST SP 800-61 framework
The Incident Response Lifecycle in 2026
1. Preparation
Preparation happens before the incident.
A mature organization should already know:
- who leads an incident;
- which systems are critical;
- how to contact legal;
- how to isolate a compromised server;
- how to revoke cloud sessions;
- where logs are stored;
- who can authorize disruptive containment;
- which regulators may apply;
- how backups will be restored.
Preparation checklist
- incident response plan;
- response RACI;
- 24/7 contact list;
- SIEM/EDR coverage;
- cloud logging;
- backup testing;
- evidence-preservation procedures;
- regulator matrix;
- vendor escalation contacts;
- communication templates.
The best incident response does not begin when the attacker arrives.
It begins when the organization designs the process beforehand.
2. Detection and Validation
Detection begins when suspicious activity is observed.
Possible sources include:
- endpoint alerts;
- SIEM detections;
- cloud logs;
- user reports;
- vendor notifications;
- threat intelligence;
- identity-provider alerts.
But an alert is not automatically an incident.
The response team first needs to determine:
- Is the activity legitimate?
- Is malicious activity confirmed?
- Which account or system is affected?
- Is the event still ongoing?
- Could the issue affect critical services or sensitive information?
Example timeline
09:12 — EDR detects credential dumping behavior.
09:18 — SOC begins investigation.
09:29 — Unauthorized use of privileged credentials confirmed.
09:34 — Incident-response lead assigned.
For a deeper look at detection performance, see Mean Time to Detect.
First 15 Minutes
For a high-severity alert:
- validate the alert;
- open an incident record;
- assign an incident ID;
- preserve initial evidence;
- identify likely affected account/system;
- escalate based on severity.
Do not begin destructive remediation before preserving evidence unless immediate action is needed to prevent serious harm.
15–30 Minutes
Establish operational control.
- appoint incident commander;
- identify technical lead;
- notify key responders;
- establish secure communication channel;
- determine whether the attacker may still have access.
The goal is to replace ad hoc reactions with coordinated response.
30–60 Minutes
Start containment planning.
Assess:
- active sessions;
- privileged accounts;
- affected systems;
- network pathways;
- cloud access;
- third-party dependencies.
This first hour often determines whether an incident stays small or expands.
3. Containment
Containment limits further attacker activity.
Potential actions include:
- isolate endpoints;
- disable compromised accounts;
- revoke authentication sessions;
- rotate API keys;
- block malicious IP addresses;
- restrict remote access;
- disable compromised integrations;
- segment affected systems.
The response team should choose containment actions based on business impact and evidence preservation.
For example:
Taking a critical production server offline immediately may stop attacker activity but also disrupt essential services and destroy volatile evidence.
The decision should therefore be documented.
Short-Term vs Long-Term Containment
Short-term containment
Designed to stop immediate harm.
Examples:
- isolate a device;
- revoke sessions;
- block attacker infrastructure.
Long-term containment
Allows business operations to continue while remediation occurs.
Examples:
- temporary network segmentation;
- alternative authentication;
- restricted service access;
- enhanced monitoring.
This distinction is useful during incidents where immediate shutdown is not operationally acceptable.
Identity Containment Is Critical
Modern incidents frequently involve identity rather than malware alone.
Response teams should consider:
- password reset;
- active session revocation;
- OAuth token revocation;
- MFA re-registration review;
- API key rotation;
- SSH key rotation;
- privileged-access review.
Simply deleting malware may leave stolen access valid.
For more on this risk, see Info Stealer Malware in 2026.
4. Investigation and Eradication
Once immediate damage is controlled, the organization needs to understand:
- how the attacker entered;
- which systems were affected;
- whether persistence exists;
- whether data was accessed;
- whether credentials were stolen;
- whether lateral movement occurred.
Eradication should remove the attacker’s ability to return.
Typical actions
- remove malware;
- delete persistence mechanisms;
- close exposed services;
- patch exploited vulnerabilities;
- rotate credentials;
- remove unauthorized accounts;
- rebuild compromised systems;
- fix misconfigurations.
Eradication should address the root cause, not just the visible symptom.
Do Not Patch Only the First Compromised Host
Suppose the attacker entered through:
VPN vulnerability → domain credential theft → lateral movement
Patching only the VPN device does not necessarily remove:
- stolen credentials;
- persistence;
- attacker-created accounts;
- malicious scheduled tasks.
The full attack path must be addressed.
For remediation planning, see Patch Management SLA Template.
Evidence Preservation During Eradication
Keep:
- endpoint logs;
- identity logs;
- cloud audit logs;
- firewall logs;
- forensic images;
- suspicious files;
- memory captures where appropriate;
- attacker communications;
- command histories.
The timeline should point to the evidence rather than attempting to contain all of it.
5. Recovery
Recovery restores operations safely.
This does not mean simply turning systems back on.
Before restoration, verify:
- attacker access removed;
- vulnerabilities remediated;
- compromised credentials reset;
- backups are clean;
- monitoring is active;
- business owner approves restoration.
Recovery sequence
- restore clean systems;
- validate configuration;
- reconnect gradually;
- monitor closely;
- confirm business functions;
- review residual risks.
Recovery Should Be Staged
For a serious attack, avoid:
restore everything at once
when possible.
A better approach is:
critical system → validation → monitoring → next system
This makes it easier to identify:
- persistence;
- reinfection;
- remaining malicious activity.
Recovery Is Not Incident Closure
A business service may be restored while the incident remains open.
Remaining activities may include:
- regulatory reporting;
- customer communication;
- root-cause investigation;
- litigation hold;
- vendor remediation;
- insurance work;
- post-incident review.
Record separately:
service restored
and:
incident closed.
6. Lessons Learned and Continuous Improvement
The incident should end with a structured review.
NIST Rev. 3 puts particular emphasis on continuous improvement and incorporating lessons back into cybersecurity risk management.
Ask:
- Why was the attack successful?
- Why was it not detected earlier?
- Which controls failed?
- Which response decisions were delayed?
- Did vendors cooperate?
- Were logs sufficient?
- Were reporting obligations identified quickly?
- Did recovery work as expected?
Post-Incident Action Register
| Finding | Corrective action | Owner | Deadline |
|---|---|---|---|
| Weak MFA | Deploy phishing-resistant MFA | IAM | 30 days |
| VPN exposure | Patch and segment | Infrastructure | 7 days |
| Log gap | Expand cloud audit logging | SOC | 14 days |
| Slow legal escalation | Update IR playbook | Legal/CISO | 14 days |
| Vendor delay | Amend notification SLA | Procurement | 60 days |
The incident is not truly “closed” until material corrective actions have owners.
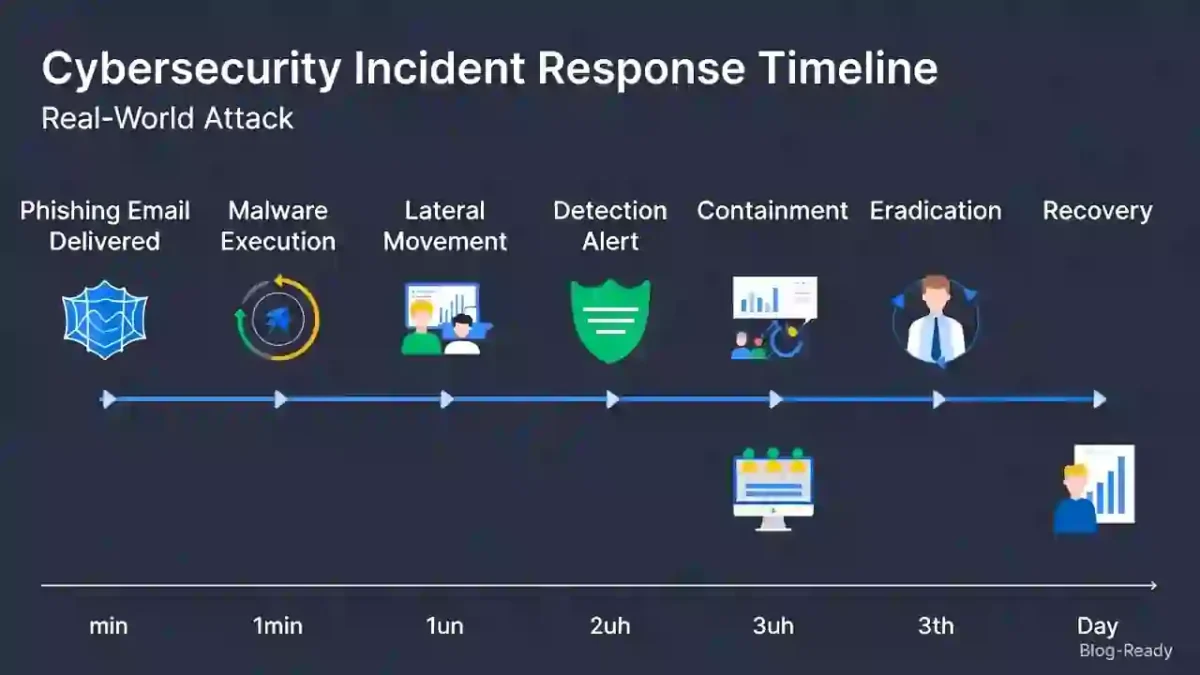
Cybersecurity Time Incident Response Timeline
A practical high-severity timeline might look like this:
| Time | Incident-response activity |
|---|---|
| 0 min | Alert generated |
| 10 min | SOC validates alert |
| 20 min | Incident record opened |
| 30 min | Incident commander assigned |
| 45 min | Evidence preservation begins |
| 1 hr | High-risk account/session containment |
| 2 hrs | Scope investigation expands |
| 4 hrs | Major affected assets identified |
| 8 hrs | Long-term containment implemented |
| 12 hrs | Legal/regulatory analysis underway |
| 24 hrs | Scope and business impact substantially clearer |
| Day 1–3 | Eradication and root-cause remediation |
| Day 2–5 | Controlled service recovery |
| Post-recovery | Lessons learned and corrective-action tracking |
This is an example, not a universal SLA. The correct target depends on severity, organization size, systems involved, and regulatory obligations.
Example Ransomware Timeline
Consider a hypothetical ransomware incident.
08:00
Employee opens malicious attachment.
08:20
Malware executes.
09:10
Credentials stolen.
10:45
Attacker begins lateral movement.
12:00
EDR identifies suspicious remote execution.
12:15
SOC validates malicious activity.
12:30
Incident declared.
12:45
Compromised accounts disabled.
13:00
Affected hosts isolated.
14:30
Evidence suggests data exfiltration.
16:00
Legal and executive teams briefed.
Day 2
Persistence removed and compromised credentials rotated.
Day 3
Critical systems restored.
Day 7
Root-cause review completed.
This illustrates a key point:
The incident-response timeline starts long before the business knows the complete story.
Regulatory Escalation Belongs Inside Incident Response
A modern incident response plan should not treat compliance as something legal examines after containment.
Different regimes use different reporting triggers.
Examples include:
- SEC materiality determination;
- UK GDPR breach awareness;
- DORA major-incident classification;
- NIS2 significant-incident awareness;
- CRA reportable incident/vulnerability;
- future CIRCIA covered-incident reporting.
For a detailed cross-border comparison, see Cyber Incident Reporting Deadlines 2026: US vs UK.
SEC Cyber Incident Example
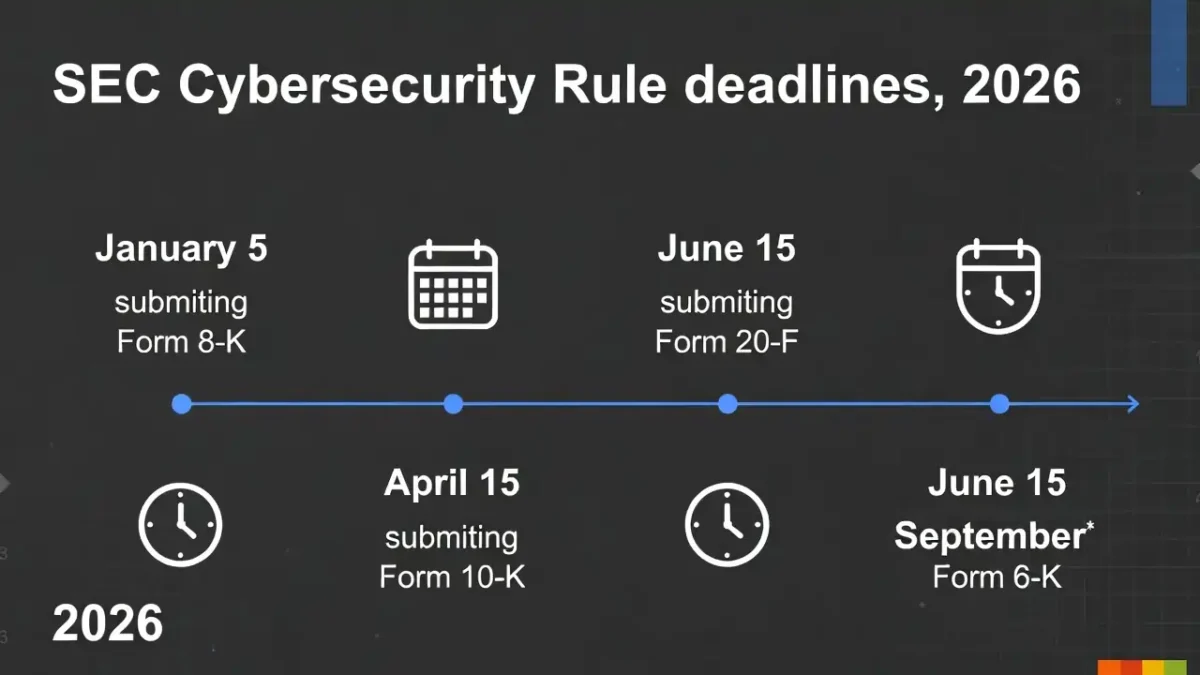
The SEC requires domestic registrants to disclose a material cybersecurity incident on Form 8-K Item 1.05 generally within four business days after determining that the incident is material. The deadline is not four days after detection, and the materiality determination must be made without unreasonable delay.
That means incident response should capture:
- detection time;
- incident confirmation;
- business impact;
- legal escalation;
- materiality determination.
For the full workflow, see SEC Cyber Incident Disclosure Checklist.
Cybersecurity Time Incident Response RACI
| Activity | Primary owner | Supporting teams |
|---|---|---|
| Alert validation | SOC | IT |
| Incident command | IR Lead | CISO |
| Evidence preservation | Forensics | IT |
| Endpoint containment | Security Operations | Infrastructure |
| Identity containment | IAM | SOC |
| Business impact | Business owner | Finance |
| Legal/regulatory review | Legal/Compliance | Security |
| Customer communication | Communications | Legal |
| Recovery authorization | Business + IT | Security |
| Lessons learned | Incident commander | All stakeholders |
This is an example model rather than a NIST requirement.
Key Incident Response Metrics
Mean Time to Detect (MTTD)
How long from attacker activity to detection?
A shorter MTTD generally limits attacker dwell time.
See Mean Time to Detect.
Mean Time to Acknowledge
How quickly does the organization begin acting after detection?
A high-quality alert provides little value if nobody investigates it for hours.
Mean Time to Contain (MTTC)
How long from validated incident to effective containment?
This is often one of the most useful operational response metrics.
Mean Time to Respond / Recover
Organizations use MTTR differently.
It may mean:
- mean time to respond;
- mean time to remediate;
- mean time to recover.
Define the metric clearly before reporting it.
Do not assume every organization’s “MTTR” means the same thing.
Dwell Time
Dwell time measures how long the attacker remains inside the environment before detection or containment, depending on the definition being used.
Long dwell time gives attackers more opportunity to:
- discover valuable assets;
- steal credentials;
- exfiltrate data;
- deploy persistence.
Cybersecurity Time Response Metrics Table
| Metric | Useful question |
|---|---|
| MTTD | How quickly did we detect the incident? |
| Time to validate | How quickly did we confirm it was real? |
| Time to escalate | How quickly did leadership/legal become involved? |
| MTTC | How quickly did we stop attacker activity? |
| Time to eradicate | How quickly did we remove the root cause? |
| Time to restore | How quickly did services return safely? |
| Regulatory decision time | How quickly did we identify reporting obligations? |
Avoid optimizing one metric at the expense of the whole response process.
How to Shorten the Incident Response Timeline
1. Improve Logging
Collect useful logs from:
- endpoints;
- identity providers;
- cloud platforms;
- VPN;
- firewalls;
- critical applications.
Detection is much slower when evidence is missing.
2. Automate High-Confidence Actions
Automation may help:
- disable known compromised accounts;
- quarantine endpoints;
- block known malicious indicators;
- collect forensic artifacts.
Human approval should remain where actions could create significant business impact.
3. Use Pre-Approved Playbooks
Develop playbooks for:
- ransomware;
- compromised credentials;
- cloud account takeover;
- malware;
- data exfiltration;
- third-party compromise.
4. Improve Network Segmentation
Segmentation can slow lateral movement and reduce blast radius.
5. Strengthen Identity Controls
Use:
- phishing-resistant MFA;
- least privilege;
- privileged access management;
- conditional access;
- session controls.
See Phishing-Resistant MFA Checklist.
6. Establish Vendor Emergency Contacts
Critical suppliers should provide:
- 24/7 security contact;
- rapid incident notification;
- evidence cooperation.
Third-party delays can lengthen the response timeline dramatically.
Use the Third-Party Risk Assessment Checklist for supplier governance.
7. Run Tabletop Exercises
Exercises should include:
- SOC;
- IT;
- legal;
- privacy;
- communications;
- executives.
A technical-only tabletop does not fully test modern incident response.
First 24 Hours Checklist
0–1 Hour
- Validate incident
- Assign incident commander
- Preserve evidence
- Begin containment
- Identify critical systems
1–4 Hours
- Assess scope
- Investigate identities
- Identify suppliers
- Establish business impact
- Escalate legal/compliance
4–12 Hours
- Expand containment
- Review persistence
- Determine likely data exposure
- Start regulatory classification
- Prepare communications
12–24 Hours
- Update executive leadership
- Confirm remediation plan
- Review regulator deadlines
- Identify customer impact
- Build recovery plan
This is a practical model, not a regulatory deadline by itself.
Common Incident Response Mistakes
Waiting for Perfect Certainty
Incidents evolve.
Use confidence levels and update findings.
Destroying Evidence During Containment
Contain quickly, but preserve critical evidence where practical.
Resetting Passwords Without Revoking Sessions
Stolen sessions may remain useful after the password changes.
Recovering Before Eradication
Restoring an infected environment can lead to reinfection.
Excluding Legal Until Late
Legal and compliance decisions may need to begin while the technical investigation is still underway.
Treating Restoration as Closure
Recovery, reporting, and lessons learned may continue after service restoration.
Using an Outdated NIST Model
Your current article links to NIST SP 800-61 Rev. 2.
Replace that link. Rev. 3 was finalized in April 2025 and supersedes Rev. 2.
Frequently Asked Questions
What is the cybersecurity incident response timeline?
It is the sequence of technical, operational, business and governance actions taken from preparation and detection through containment, remediation, recovery and post-incident improvement.
What are the six incident response phases?
A practical six-phase operating model is:
- Preparation
- Detection and validation
- Containment
- Investigation and eradication
- Recovery
- Lessons learned
However, NIST SP 800-61 Rev. 3 integrates incident response into CSF 2.0 rather than prescribing this exact six-step list.
Is NIST SP 800-61 Rev. 2 still current?
No.
NIST finalized SP 800-61 Rev. 3 on April 3, 2025, superseding Rev. 2.
How fast should an organization contain a cyberattack?
There is no universal containment deadline.
Severity, business impact, system type, evidence requirements and operational constraints all matter.
Organizations should establish risk-based internal targets and track actual performance.
What is the difference between MTTD and MTTC?
MTTD measures detection speed.
MTTC measures how quickly an incident is contained after the relevant starting point defined by the organization.
Be explicit about definitions when reporting metrics.
Does SEC reporting begin when security detects the incident?
No.
For domestic registrants, the Form 8-K Item 1.05 deadline is generally four business days after the company determines the cybersecurity incident is material.
Does paying a ransomware demand remove SEC disclosure requirements?
No. SEC guidance says that if a registrant has already determined an incident is material, a subsequent ransom payment and restoration of operations does not eliminate the Item 1.05 disclosure requirement.
Should incident response include third parties?
Yes.
Cloud providers, MSPs and other suppliers may hold critical evidence or even discover the incident first.
When should lessons learned happen?
After immediate response and recovery are stable enough for meaningful review, while evidence and decision context are still fresh.
Final Takeaway
A cybersecurity incident response timeline should not be viewed as:
six boxes on a diagram.
It is a coordinated decision process that runs from readiness before the attack through recovery and organizational improvement afterward.
The strongest sequence is:
prepare → detect → validate → contain → investigate → eradicate → recover → improve
with regulatory and business decisions happening alongside the technical response.
NIST’s current SP 800-61 Rev. 3 reinforces this broader model by integrating incident response across the NIST Cybersecurity Framework 2.0 instead of treating it as an isolated SOC activity.
The most valuable response metric is therefore not simply:
“How fast did we close the incident?”
It is:
“How quickly did we understand enough to make the right containment, business, legal and recovery decisions?”
That is a much stronger measure of incident-response maturity.
Primary External Sources
Use these primary sources at the bottom of the article:
- NIST SP 800-61 Rev. 3 — Incident Response Recommendations
- NIST Incident Response Project
- SEC Cybersecurity Disclosure Guide
NIST confirms that Rev. 3 supersedes Rev. 2 and integrates incident response into CSF 2.0.