Mean Time to Respond (MTTR) in Cybersecurity: Formula, Metrics and How to Improve It
Mean Time to Respond (MTTR) is a cybersecurity operations metric used to measure how long it takes a security team to move from detecting or validating an incident to taking an agreed response action.
The exact definition matters.
The acronym MTTR is used inconsistently across the technology industry. Depending on the organization, it may mean:
- Mean Time to Respond;
- Mean Time to Remediate;
- Mean Time to Recover;
- Mean Time to Repair.
Those are not the same thing.
For this article, MTTR means Mean Time to Respond.
A practical definition is:
The average elapsed time between a defined incident-response starting point and the point at which the organization has taken the response action specified by its measurement policy.
That starting point may be:
- detection;
- alert acknowledgement;
- incident validation.
The end point may be:
- containment initiated;
- containment completed;
- another clearly defined response milestone.
The important requirement is consistency.
A security team should never report “MTTR = 45 minutes” unless everyone knows exactly:
45 minutes from what → to what?
NIST’s current SP 800-61 Rev. 3, finalized in April 2025, integrates incident response across the NIST Cybersecurity Framework 2.0 and emphasizes improving the effectiveness of incident detection, response, and recovery. It supersedes SP 800-61 Rev. 2.
MTTR at a Glance
| Metric | What it measures |
|---|---|
| MTTD | Malicious activity / chosen start → detection |
| MTTA | Alert → analyst acknowledgement |
| Time to Validate | Alert → confirmed incident |
| MTTR | Defined response start → defined response action |
| MTTC | Validated incident → effective containment |
| Remediation Time | Incident → root cause/security fixes completed |
| Recovery Time | Incident → trusted business service restored |
| Dwell Time | Attacker presence before discovery/detection |
The strongest security programs measure several of these rather than relying on one “MTTR” number.
Table of Contents
What Is Mean Time to Respond?
Mean Time to Respond measures the average time required for a security team to take meaningful action after a defined response trigger.
A useful internal definition might be:
Incident validated → effective containment action
Another organization might define it as:
High-severity alert acknowledged → containment initiated
Both can be valid.
What is not valid is switching definitions between incidents.
For example:
- Incident A: detection → isolation
- Incident B: acknowledgement → remediation
- Incident C: detection → full recovery
Averaging those three values produces a metric that has little operational meaning.
MTTR Formula
The basic formula is:
MTTR = Total Response Time ÷ Number of Incidents
Suppose a security team defines Mean Time to Respond as:
Time from incident validation to effective containment.
The team reviews four incidents:
| Incident | Validated | Contained | Response time |
|---|---|---|---|
| A | 09:00 | 09:20 | 20 min |
| B | 10:30 | 11:15 | 45 min |
| C | 13:00 | 13:15 | 15 min |
| D | 15:00 | 16:00 | 60 min |
Total response time:
20 + 45 + 15 + 60 = 140 minutes
Number of incidents:
4
Therefore:
MTTR = 140 ÷ 4 = 35 minutes
Your Mean Time to Respond is 35 minutes for that population and definition.
Why the Definition Matters More Than the Formula
The arithmetic is easy.
The measurement policy is the difficult part.
Your organization should document:
Start event: incident validation
End event: effective containment
Population: High and Critical incidents
Time basis: 24/7 elapsed time
Excluded events: test alerts and false positives
Now the metric can be compared over time.
Without that definition, MTTR can become a vanity number.
Mean vs Median Response Time
Like MTTD, MTTR can be distorted by outliers.
Suppose response times are:
10, 14, 18, 20, 240 minutes
The unusually slow 240-minute case raises the mean significantly.
Reporting only the average hides the fact that:
- most incidents were handled quickly;
- one incident suffered a serious response delay.
A stronger dashboard should include:
- mean;
- median;
- P90;
- P95;
- worst-case response time.
Example MTTR Dashboard
| Metric | Current |
|---|---|
| Mean response time | 41 min |
| Median response time | 22 min |
| P90 | 2.4 hrs |
| P95 | 5.1 hrs |
| Critical-incident MTTR | 12 min |
| High-severity MTTR | 31 min |
| Vendor-dependent incident MTTR | 3.6 hrs |
This immediately shows that vendor-dependent incidents may be creating the largest delay.
MTTR vs MTTD
These metrics measure different stages.
MTTD
Measures how long it takes to detect an incident.
Example:
Attack starts 08:00 → detected 08:30
MTTD interval:
30 minutes
MTTR
Measures how long it takes to respond after the chosen response starting point.
Example:
Incident validated 08:40 → account disabled and host isolated 09:00
Response interval:
20 minutes
A team can have:
excellent detection + poor response
or:
poor detection + excellent response
Both should be visible.
For the detection metric, see Mean Time to Detect (MTTD).
MTTR vs Mean Time to Contain
These two may overlap depending on your definition.
If your organization defines Mean Time to Respond as:
validated incident → containment
then MTTR and MTTC may effectively measure the same interval.
That creates unnecessary metric duplication.
A cleaner model is:
MTTD: attack → detection
MTTA: alert → acknowledgement
Validation time: acknowledgement → incident confirmed
MTTC: confirmed incident → contained
Recovery time: contained → trusted operation restored
Then reserve MTTR as a broader organizational KPI only if there is a clear reason.
For the containment metric, see Mean Time to Contain (MTTC).
MTTR vs Dwell Time
Dwell time measures attacker presence before discovery or detection, depending on the research definition.
MTTR measures what the defensive organization does after its response trigger.
Mandiant’s M-Trends 2026 reports a global median dwell time of 14 days across its 2025 investigations, up from 11 days in the previous reporting period.
That figure should not be presented as an “average MTTR.”
They are different metrics.
For the full distinction, see Dwell Time Cybersecurity.
Why Response Time Matters
Once a real incident has been identified, delay can give an attacker more opportunity to:
- escalate privileges;
- steal credentials;
- move laterally;
- exfiltrate data;
- deploy ransomware;
- destroy backups;
- disrupt operations.
Mandiant’s 2026 research highlights how compressed some attack timelines have become. It reports that the median hand-off time between initial-access actors and secondary threat groups fell to 22 seconds in its 2025 data.
The lesson is not that every organization must respond in 22 seconds.
The lesson is that response playbooks should assume some attacks can escalate extremely quickly.
Verizon 2026: Why Response Scope Is Getting Harder
Verizon’s 2026 DBIR reports that vulnerability exploitation accounted for 31% of breach entry points in its dataset and that third-party involvement rose sharply.
This affects response because teams may need to coordinate across:
- endpoint security;
- vulnerable infrastructure;
- suppliers;
- cloud providers;
- identity systems;
- external incident responders.
A modern MTTR program should therefore measure response delays caused by third parties separately.
There Is No Universal “Good MTTR”
Your current article says high-performing organizations aim to contain threats within hours rather than days.
That can be directionally useful, but it should not be presented as a universal industry benchmark.
A good response target depends on the event.
For example:
| Incident type | Illustrative response target |
|---|---|
| Active ransomware execution | Minutes |
| Privileged account takeover | Minutes |
| Cloud administrator compromise | Minutes |
| Critical server malware | Minutes to <1 hr |
| Suspicious data transfer | <1 hr |
| Low-severity endpoint malware | Risk-based |
These are example internal targets, not regulatory requirements or industry standards.
Use Severity-Based MTTR Targets
A mature organization should not expect the same response speed for every event.
Example:
| Severity | Internal target |
|---|---|
| Critical | <15 min |
| High | <30 min |
| Medium | <2 hrs |
| Low | <8 hrs |
Again, these are illustrative.
Each organization should design targets around:
- business impact;
- attack speed;
- system criticality;
- staffing;
- automation;
- regulatory context.
Measure Response Time by Incident Type
An overall MTTR may hide serious weaknesses.
For example:
| Incident type | Average response |
|---|---|
| Endpoint malware | 14 min |
| Identity compromise | 22 min |
| Cloud compromise | 58 min |
| Third-party incident | 4.2 hrs |
| Data exfiltration | 46 min |
Now leadership can see where the real response bottleneck exists.
Measure Response Time by Action
A single response metric can also hide slow hand-offs.
Track:
| Response step | Time |
|---|---|
| Alert → acknowledgement | 6 min |
| Acknowledgement → validation | 11 min |
| Validation → incident commander | 4 min |
| Incident commander → containment decision | 8 min |
| Decision → technical containment | 9 min |
| Technical containment → legal escalation | 22 min |
The real issue may not be “MTTR.”
It may be:
legal escalation is too slow
or:
containment approval is too slow.
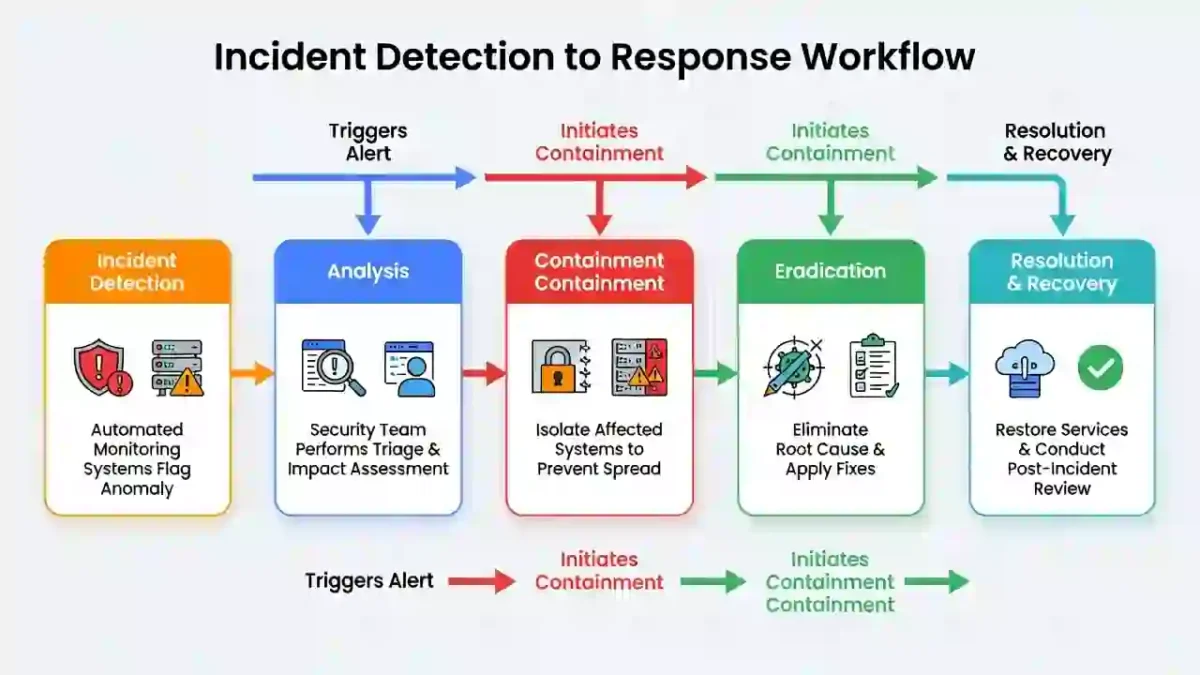
Cybersecurity Time Response Funnel
A useful sequence is:
Detection
↓
Acknowledgement
↓
Validation
↓
Escalation
↓
Containment
↓
Eradication
↓
Recovery
Measure each transition.
Do not compress the entire workflow into one average unless that is genuinely useful.
7 Practical Ways to Reduce Response Time
1. Automate High-Confidence Containment
Automation can shorten response to known, high-confidence threats.
Examples include:
- isolate endpoint;
- disable account;
- revoke session;
- block malicious IP;
- disable token.
But automation should be risk-aware.
Automatically shutting down a hospital system or production database based on a weak alert may create more damage than the attacker.
Use automation where:
- confidence is high;
- action is reversible;
- business impact is understood.
2. Define Escalation Procedures Before the Incident
A common source of delay is uncertainty about ownership.
Your playbook should answer:
- Who owns Critical incidents?
- Who can isolate production?
- Who can disable privileged accounts?
- When does legal join?
- When does executive leadership join?
- Who calls the vendor?
- Who communicates with customers?
NIST’s current incident-response guidance emphasizes integrating incident response throughout organizational cybersecurity risk management, which requires clear roles and communication rather than isolated SOC action.
3. Pre-Approve Common Response Actions
Some decisions should not require an emergency executive meeting every time.
Examples:
- isolate employee laptop;
- revoke suspicious user session;
- block confirmed malicious domain;
- reset compromised standard account.
Document:
- which actions are pre-authorized;
- which require management approval;
- which require business-owner approval.
This can remove significant response delay.
4. Conduct Incident Response Exercises
Tabletop exercises expose slow decisions before a real incident.
Test scenarios such as:
- ransomware;
- cloud takeover;
- privileged account compromise;
- data exfiltration;
- supplier compromise.
Include:
- SOC;
- IT;
- legal;
- privacy;
- business leadership;
- communications.
For the full lifecycle, see Cybersecurity Incident Response Timeline.
5. Use Centralized Incident Case Management
Response slows down when evidence is scattered across:
- email;
- chat;
- spreadsheets;
- ticketing systems;
- analyst notebooks.
A central incident record should contain:
- timeline;
- owners;
- evidence references;
- actions;
- decisions;
- regulator considerations;
- outstanding tasks.
Use the Data Breach Timeline Template for a practical chronology structure.
6. Integrate Detection and Response Tools
Connecting telemetry with response tools can reduce manual hand-offs.
Useful integrations may include:
- SIEM → SOAR;
- EDR → isolation;
- identity provider → session revocation;
- ticketing → incident creation;
- cloud security → access restriction.
The goal is not automation for its own sake.
It is fewer unnecessary hand-offs between:
detection → decision → action.
7. Improve Third-Party Response Agreements
Supplier incidents can make internal MTTR look poor even when your security team acts quickly.
Contracts should define:
- 24/7 security contacts;
- notification SLA;
- evidence sharing;
- status-update cadence;
- containment cooperation;
- incident escalation.
Verizon’s 2026 DBIR reports a significant rise in third-party involvement in breaches, making this increasingly important.
For governance, see Third-Party Risk Assessment Checklist.
Response Time and Regulatory Readiness
MTTR is not itself a legal deadline.
But slow response can make regulatory compliance harder.
For example:
SEC
The SEC generally requires a domestic registrant to file Item 1.05 Form 8-K within four business days after determining that a cybersecurity incident is material. The deadline is not tied directly to discovery, and materiality must be determined without unreasonable delay.
Security teams therefore need to provide reliable information to legal and leadership quickly enough for a defensible materiality review.
Response Time vs SEC Materiality Time
These should remain separate metrics.
Example:
09:00 — Incident detected
09:15 — Incident validated
09:32 — Containment completed
12:00 — Business impact analysis begins
Next day 10:00 — Materiality determined
Operational MTTR may be:
17 minutes
while the securities-law decision process takes much longer.
Both can be valid.
Do not merge them.
Response Time and UK/EU Reporting
Other regimes may use different triggers.
Examples include:
- UK GDPR breach awareness;
- DORA major-incident classification;
- NIS2 significant-incident awareness;
- CRA incident/vulnerability awareness;
- proposed CIRCIA covered-event reporting.
For a detailed comparison, see Cyber Incident Reporting Deadlines 2026: US vs UK.
Example Ransomware Response Timeline
Consider a ransomware event.
08:00 — EDR detects suspicious PowerShell execution.
08:06 — Analyst acknowledges alert.
08:14 — Incident validated.
08:20 — Incident commander assigned.
08:25 — Compromised user sessions revoked.
08:31 — Endpoint isolated.
08:45 — Similar activity found on second host.
09:05 — Network containment expanded.
10:30 — No additional lateral movement observed.
Depending on your internal definition:
MTTA = 6 minutes
Validation time = 8 minutes
MTTC = 17 minutes
This tells you much more than saying:
MTTR = 31 minutes.
Example Cloud Account-Takeover Timeline
14:00 — Impossible-travel alert generated.
14:08 — Analyst reviews alert.
14:18 — Unauthorized OAuth application discovered.
14:25 — Incident declared.
14:31 — Sessions revoked.
14:36 — OAuth consent removed.
14:50 — Privileged role review completed.
This incident has multiple measurable transitions.
Track them separately.
Mean Time to Respond and Dwell Time Together
A mature security program can display:
| Metric | Result |
|---|---|
| Median dwell time | 2.1 hrs |
| MTTD | 32 min |
| MTTA | 6 min |
| Validation time | 9 min |
| MTTC | 18 min |
| Recovery time | 6.4 hrs |
Now leadership sees the complete chain.
Common MTTR Measurement Mistakes
1. Not Defining What “R” Means
Respond?
Remediate?
Repair?
Recover?
Define it.
2. Mixing Start Points
Do not use detection for one incident and validation for another.
3. Mixing End Points
Containment and full recovery are completely different milestones.
4. Using Only the Mean
Track median and percentiles too.
5. Treating All Severity Levels Equally
Critical ransomware and low-risk malware should not have identical response targets.
6. Ignoring Business Approval Delays
Sometimes the SOC is fast but the organization is slow.
Measure:
decision → action
separately.
7. Ignoring Supplier Delay
Track vendor-dependent incidents independently.
8. Automating Without Quality Controls
Poor automation can contain the wrong systems and create outages.
Cybersecurity Time Response Scorecard
A practical quarterly scorecard could look like this:
| Metric | Q1 | Q2 | Q3 |
|---|---|---|---|
| MTTA | 11 min | 8 min | 5 min |
| Validation time | 22 min | 17 min | 12 min |
| MTTC | 54 min | 39 min | 28 min |
| Critical MTTC | 19 min | 14 min | 10 min |
| Recovery time | 14 hrs | 11 hrs | 8 hrs |
| Vendor-related MTTC | 5.1 hrs | 4.4 hrs | 3.6 hrs |
This makes operational improvements much easier to identify.
A 90-Day Response-Time Improvement Plan
Days 1–30: Measure
Define:
- MTTD;
- MTTA;
- validation time;
- MTTC;
- recovery time.
Capture baseline data.
Days 31–60: Fix Bottlenecks
Identify:
- queue delays;
- approval delays;
- missing integrations;
- vendor delays;
- poor playbooks.
Days 61–90: Test
Run:
- ransomware drill;
- account-takeover drill;
- third-party compromise drill.
Compare new results against baseline.
Questions the CISO Should Ask
Instead of:
“What is our MTTR?”
ask:
- How quickly do we acknowledge Critical alerts?
- How quickly do we validate true incidents?
- How quickly can we isolate compromised identities?
- Which containment actions require approval?
- Which suppliers slow us down?
- What is our P90 containment time?
- Which incident classes routinely miss target?
Those questions generate more useful security decisions.
Frequently Asked Questions
What does MTTR mean in cybersecurity?
It can mean several things.
Common uses include Mean Time to Respond, Remediate, Recover, or Repair.
Your organization should explicitly define the term.
What is Mean Time to Respond?
It is the average elapsed time between a defined incident-response starting point and a defined response action.
What is the MTTR formula?
MTTR = Total Response Time ÷ Number of Incidents
The formula is meaningful only when all incidents use the same start and end points.
What is a good MTTR?
There is no universal benchmark.
Appropriate targets depend on:
- incident severity;
- attack speed;
- system criticality;
- staffing;
- automation;
- business constraints.
Is MTTR the same as MTTD?
No.
MTTD measures detection speed.
MTTR measures response speed according to your defined response interval.
Is MTTR the same as MTTC?
Not necessarily.
If your organization defines Mean Time to Respond as time to containment, the metrics may overlap.
A clearer program should avoid redundant definitions.
Is MTTR the same as recovery time?
Only if your organization explicitly defines MTTR as Mean Time to Recover.
This article uses MTTR to mean Mean Time to Respond.
Does lower MTTR always mean better security?
Not automatically.
An organization can reduce MTTR by automatically isolating systems, but poorly designed automation can create unnecessary business disruption.
Response speed must be balanced with:
- detection confidence;
- business impact;
- evidence preservation.
Is NIST SP 800-61 Rev. 2 still current?
No.
NIST finalized SP 800-61 Rev. 3 on April 3, 2025, superseding Rev. 2.
Final Takeaway
Mean Time to Respond is useful only when your organization defines what “respond” actually means.
The basic formula is simple:
total response time ÷ incidents = MTTR
But a mature security program should go further.
Instead of one ambiguous number, measure:
MTTD → MTTA → validation time → MTTC → eradication time → recovery time
That produces a much clearer view of incident-response performance.
Current threat research makes this especially important. Mandiant’s 2026 findings show both ends of the spectrum: some attackers maintain long-term stealth, while criminal hand-offs can occur in seconds. Verizon’s 2026 DBIR also shows vulnerability exploitation and third-party compromise playing a growing role in breaches.
So the right executive question is not:
“Is our MTTR low?”
It is:
“Where exactly does our response slow down, and can we remove that delay without creating new operational risk?”
That is a much stronger cybersecurity performance question.
Primary External Sources
Use these authoritative external references at the bottom of the WordPress article: