SOC Efficiency Metrics 2026: 10 KPIs for Detection, Triage, Containment and Recovery
A Security Operations Center should not be judged by the number of alerts it closes.
A SOC exists to reduce cyber risk by identifying meaningful threats, validating them quickly, containing attacker activity, coordinating response, and helping the organization recover safely.
That makes SOC efficiency metrics essential.
But efficiency does not mean:
“close more tickets.”
A SOC can close thousands of alerts and still perform poorly if:
- serious threats remain undetected;
- analysts acknowledge critical alerts too slowly;
- containment takes hours;
- false positives consume most analyst time;
- third-party incidents are discovered by outsiders;
- recovery regularly stalls;
- regulatory escalation happens too late.
The strongest SOC dashboards therefore measure the entire operational chain:
telemetry → detection → acknowledgement → triage → validation → containment → recovery
NIST’s current SP 800-61 Rev. 3, finalized in April 2025, integrates incident response into the NIST Cybersecurity Framework 2.0 and specifically aims to improve the efficiency and effectiveness of incident detection, response, and recovery.
In 2026, a useful SOC dashboard should answer three questions:
How quickly are we finding real threats?
How efficiently are we turning alerts into defensive action?
Where are the delays that create the most business risk?
SOC Efficiency Metrics at a Glance
| Metric | Main question |
|---|---|
| Mean Time to Detect (MTTD) | How quickly do we detect malicious activity? |
| Mean Time to Acknowledge (MTTA) | How quickly does an analyst begin action? |
| Alert Triage Time | How quickly are alerts classified and prioritized? |
| Alert Backlog Age | How long are unresolved alerts waiting? |
| Mean Time to Contain (MTTC) | How quickly do we effectively stop further harm? |
| Mean Time to Respond (MTTR) | How quickly do we reach the defined response milestone? |
| Dwell Time | How long did an attacker remain undiscovered? |
| False Positive Rate | How much analyst effort is wasted on non-threats? |
| Automation Coverage | Which repeatable actions are handled automatically? |
| Recovery / Incident Completion Time | How quickly does the organization return to trusted operation? |
These metrics should not be treated as universal industry benchmarks.
Each organization should define:
- start point;
- end point;
- incident population;
- severity;
- data source;
- calculation method.
Table of Contents
Why SOC Efficiency Metrics Matter
Modern SOC teams face several simultaneous pressures.
Threat activity is becoming faster in some cases while remaining highly stealthy in others.
Mandiant’s M-Trends 2026 reports that global median attacker dwell time across its 2025 investigations increased to 14 days, while some criminal initial-access hand-offs occurred in less than 30 seconds. It also reports that organizations first detected malicious activity internally in 52% of investigated incidents.
Verizon’s 2026 DBIR reports that vulnerability exploitation became the leading breach entry point in its dataset at 31%, while third-party involvement rose substantially.
That means a modern SOC must handle both:
slow, hidden compromise
and:
rapid attack progression.
SOC metrics help identify whether the organization is prepared for both.
Metric 1: Mean Time to Detect (MTTD)
Mean Time to Detect measures average detection speed according to an organization’s chosen definition.
A simple formula is:
MTTD = Total Detection Time ÷ Number of Incidents
For example:
| Incident | Malicious activity | Detection | Interval |
|---|---|---|---|
| A | 08:00 | 08:20 | 20 min |
| B | 10:00 | 11:00 | 60 min |
| C | 14:00 | 14:10 | 10 min |
Total detection time:
90 minutes
MTTD:
90 ÷ 3 = 30 minutes
The important question is not merely the arithmetic.
It is:
What starts the clock?
Your SOC might choose:
first confirmed malicious activity → detection
Another organization may use:
first observable malicious activity → alert generation
Both can work if they are documented and applied consistently.
For the full methodology, see Mean Time to Detect (MTTD).
MTTD Should Not Be Used Alone
A low MTTD does not automatically mean the SOC is effective.
Example:
MTTD = 7 minutes
but:
containment = 4 hours later
The team detected the problem quickly but failed to control it.
MTTD should therefore be paired with:
- acknowledgement time;
- validation time;
- containment time;
- recovery time.
Metric 2: Mean Time to Acknowledge (MTTA)
Your current article is missing a numbered #2.
I strongly recommend making Mean Time to Acknowledge the second core metric.
MTTA measures how quickly an analyst or responder acknowledges a security alert or incident after it is generated.
A simple formula is:
MTTA = Total Alert-to-Acknowledgement Time ÷ Number of Alerts or Incidents
Example:
10:00 — Critical EDR alert generated
10:08 — Analyst begins investigation
MTTA:
8 minutes
This metric helps separate:
detection technology performance
from:
human operational delay.
Why MTTA Matters
Imagine two SOCs.
SOC A
Alert generated: 09:00
Analyst review: 09:03
SOC B
Alert generated: 09:00
Analyst review: 10:20
Both tools detected the same threat at the same time.
Only one SOC acted quickly.
A high MTTA may indicate:
- understaffing;
- poor queue prioritization;
- excessive alert volume;
- unclear ownership;
- weak escalation.
Metric 3: Alert Triage Time
Alert triage time measures how long it takes analysts to determine what an alert represents and what should happen next.
Triage might classify an alert as:
- false positive;
- benign activity;
- suspicious event;
- confirmed incident;
- Critical incident requiring escalation.
A useful measurement is:
alert acknowledgement → initial disposition
Example:
09:10 — Analyst acknowledges
09:24 — Alert classified as confirmed account takeover
Triage time:
14 minutes
Why Triage Time Matters
A SOC can have excellent alerting but still suffer slow incident response if analysts need too long to determine:
- what happened;
- how severe it is;
- who owns the next action.
Slow triage often comes from:
- missing context;
- poor asset data;
- fragmented tools;
- weak playbooks;
- alert overload.
Track Triage by Severity
Do not combine every alert into one average.
A useful dashboard could show:
| Severity | Median triage time |
|---|---|
| Critical | 6 min |
| High | 11 min |
| Medium | 28 min |
| Low | 2.4 hrs |
These are illustrative values, not universal benchmarks.
Metric 4: Alert Backlog Age
Alert backlog volume tells you how many items are open.
Alert backlog age tells you something more important:
how long unresolved work is sitting in the queue.
A SOC may have only 150 alerts outstanding but still be in poor condition if some Critical or High alerts have waited hours.
Track:
- oldest alert;
- median backlog age;
- P90 backlog age;
- Critical alerts beyond SLA;
- High alerts beyond SLA.
Example Backlog Dashboard
| Metric | Result |
|---|---|
| Open alerts | 420 |
| Median age | 24 min |
| P90 age | 3.1 hrs |
| Oldest Critical alert | 7 min |
| Oldest High alert | 48 min |
| Alerts over SLA | 18 |
This provides more operational insight than simply:
420 open alerts.
Metric 5: Mean Time to Contain (MTTC)
Mean Time to Contain measures how long it takes to effectively limit additional harm after the chosen incident-response trigger.
A useful internal definition might be:
confirmed incident → effective containment
Containment could include:
- endpoint isolation;
- account disablement;
- session revocation;
- token revocation;
- malicious IP blocking;
- segmentation;
- compromised integration shutdown.
A simple formula is:
MTTC = Total Containment Time ÷ Number of Incidents
For the full calculation methodology, see Mean Time to Contain (MTTC).
Containment Must Be Effective
A response action is not automatically containment.
Example:
09:00 — laptop isolated
but:
09:12 — attacker still has active cloud administrator token
The endpoint may be isolated.
The incident is not fully contained.
Track:
containment action initiated
and:
effective containment confirmed
separately where practical.
Metric 6: Mean Time to Respond (MTTR)
MTTR is one of the most ambiguous metrics in cybersecurity.
It can mean:
- Mean Time to Respond;
- Mean Time to Recover;
- Mean Time to Repair;
- Mean Time to Remediate.
For Cybersecurity Time, we use MTTR to mean Mean Time to Respond and recommend always stating the exact start and end points.
For example:
incident validation → first approved response action
A formula is:
MTTR = Total Response Time ÷ Number of Incidents
For a deeper explanation, see Mean Time to Respond.
Do Not Let MTTR Become a Catch-All Metric
A dashboard that says:
MTTR = 3 hours
is not useful unless executives know whether that means:
- acknowledged;
- contained;
- remediated;
- recovered.
A better SOC uses several defined metrics rather than forcing the entire incident lifecycle into one number.
Metric 7: Dwell Time
Dwell time generally describes how long an attacker remains in an environment before discovery or detection.
Mandiant’s M-Trends 2026 reports a global median dwell time of 14 days across its 2025 incident-response investigations, compared with 11 days previously.
That is a useful external research statistic.
It should not be presented as:
“the average MTTD for all organizations.”
Dwell time and MTTD are related but not identical.
For the dedicated guide, see Dwell Time Cybersecurity.
Internal vs External Discovery Is a Useful Companion Metric
Mandiant’s 2026 data also reports that organizations first detected evidence of malicious activity internally 52% of the time in its 2025 investigations.
A SOC should therefore consider tracking:
internally detected incidents %
versus:
externally discovered incidents %
External discovery sources may include:
- supplier;
- customer;
- researcher;
- law enforcement;
- threat actor.
If major incidents are frequently discovered externally, detection capability may have serious gaps.
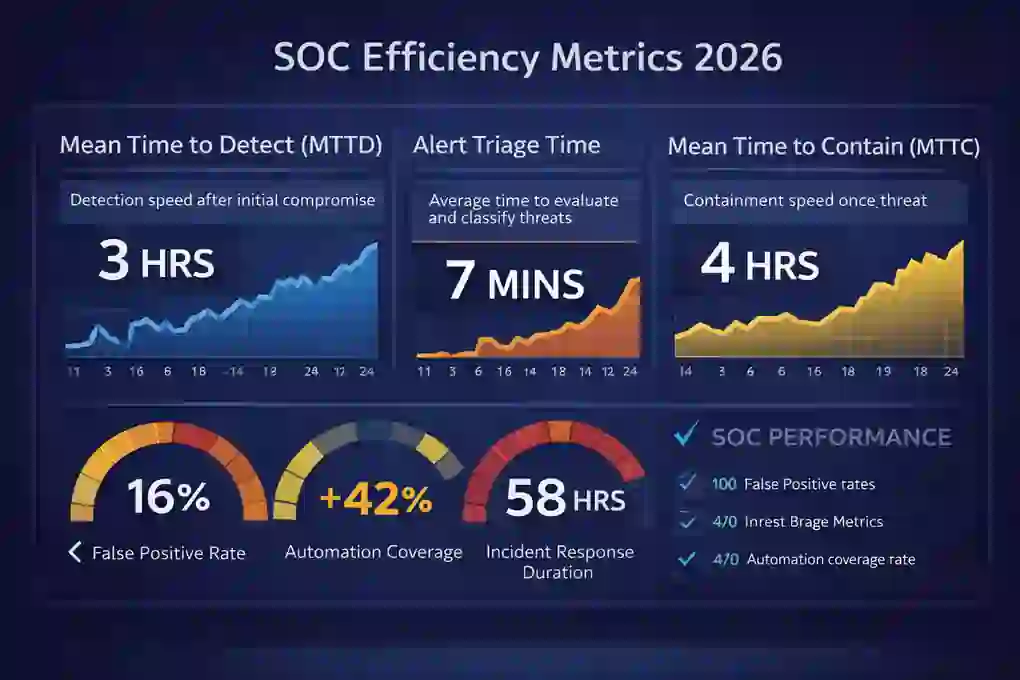
Metric 8: False Positive Rate
False-positive rate measures how much alert volume turns out not to represent actionable malicious activity.
A simplified calculation is:
False Positive Rate = False Positive Alerts ÷ Total Alerts Reviewed × 100
Example:
1,000 alerts reviewed
250 false positives
250 ÷ 1,000 × 100 = 25%
But use caution.
Different SOCs classify alerts differently, so cross-company comparisons can be misleading.
Why False Positives Matter
Too many poor-quality alerts can create:
- analyst fatigue;
- longer queue times;
- slower acknowledgement;
- slower validation;
- missed real threats.
A lower false-positive rate is usually useful only if the SOC is not also missing real attacks.
Aggressively suppressing alerts merely to make a dashboard look better creates risk.
Add Alert-to-Incident Conversion Rate
A useful companion metric is:
Alert-to-Incident Conversion Rate
Example:
10,000 alerts
250 confirmed incidents
Conversion:
2.5%
This helps leadership understand whether the SOC is processing huge alert volume for relatively little actionable output.
Metric 9: Automation Coverage
Automation coverage measures how much appropriate repetitive SOC work is automated.
Potential automated tasks include:
- enriching alerts;
- querying threat intelligence;
- collecting endpoint context;
- opening incident records;
- quarantining confirmed malicious email;
- blocking high-confidence malicious infrastructure;
- isolating endpoints under defined conditions.
But automation should not be measured simply by:
“percentage of alerts touched by automation.”
The more useful question is:
Which manual steps are being removed, and does that improve response without increasing errors?
Measure Automation Outcomes
Track:
- analyst minutes saved;
- acknowledgement improvement;
- triage-time improvement;
- containment-time improvement;
- automated action failure rate;
- rollback rate;
- false containment rate.
SANS guidance on SOC metrics emphasizes that metrics should be developed with organizational stakeholders and aligned to business objectives rather than selected in isolation.
AI Automation Should Be Measured Carefully
AI-assisted SOC tools can help:
- summarize alerts;
- correlate events;
- enrich investigations;
- recommend next steps.
But metrics should also monitor:
- incorrect classifications;
- analyst overrides;
- automated action errors;
- false-positive reduction;
- investigation quality.
Do not assume:
more AI automation = better SOC efficiency.
Efficiency depends on useful outcomes.
Metric 10: Recovery and Incident Completion Time
Your current article uses Incident Response Completion Time.
The concept is useful, but it should be defined more precisely.
I recommend tracking at least two separate events:
Service Recovery Time
When did affected business operations return to a trusted state?
Incident Closure Time
When was the incident formally closed after:
- investigation;
- eradication;
- reporting;
- recovery;
- lessons learned
were complete?
These can be very different.
Example
Monday 10:00 — Incident declared.
Tuesday 16:00 — Critical service restored.
Recovery time:
30 hours
Friday 14:00 — Root cause confirmed and incident formally closed.
Incident closure time:
100 hours
A single “completion time” would hide that distinction.
Why Recovery Metrics Matter
Fast containment is valuable, but business leaders also care about:
- downtime;
- service restoration;
- customer impact;
- residual risk.
NIST SP 800-61 Rev. 3 explicitly treats recovery as a core part of incident response and broader cybersecurity risk management.
For the full lifecycle, see Cybersecurity Incident Response Timeline.
Cybersecurity Time SOC Efficiency Funnel
A useful SOC measurement chain is:
Telemetry
↓
Alert
↓
Acknowledgement
↓
Triage
↓
Validation
↓
Response
↓
Containment
↓
Eradication
↓
Recovery
↓
Closure
Each transition can be measured separately.
That is more useful than relying on one broad “SOC efficiency score.”
Recommended SOC Dashboard
| KPI | Current | Target | Trend |
|---|---|---|---|
| Median MTTD | 18 min | <15 min | Improving |
| MTTA | 5 min | <5 min | Stable |
| Critical triage | 7 min | <10 min | Good |
| P90 backlog age | 2.2 hrs | <2 hrs | Needs work |
| Median MTTC | 21 min | <20 min | Improving |
| MTTR | 16 min | <15 min | Improving |
| Internal discovery | 81% | >85% | Improving |
| False positive rate | 19% | <15% | Needs work |
| Automation-assisted cases | 58% | Risk-based | Improving |
| Recovery time | 7.2 hrs | <6 hrs | Needs work |
These numbers are illustrative.
Do not publish them as universal benchmarks.
Why Mean Alone Is Not Enough
A SOC may report:
Average MTTC = 28 minutes
That sounds strong.
But imagine the underlying data:
10, 12, 15, 18, 85 minutes
The long incident matters.
Leadership should therefore see:
- mean;
- median;
- P90;
- P95;
- maximum.
This exposes slow-tail incidents that averages can hide.
Segment Metrics by Severity
Do not compare Critical and Low-severity events as one population.
Example:
| Severity | MTTD | MTTC |
|---|---|---|
| Critical | 7 min | 11 min |
| High | 18 min | 25 min |
| Medium | 41 min | 1.2 hrs |
| Low | 2.6 hrs | 5.4 hrs |
These are illustrative internal targets.
They are not global standards.
Segment Metrics by Incident Type
A SOC dashboard can also compare:
| Incident type | MTTD | MTTC |
|---|---|---|
| Ransomware | 8 min | 13 min |
| Identity compromise | 17 min | 20 min |
| Cloud compromise | 43 min | 47 min |
| Data exfiltration | 52 min | 58 min |
| Third-party compromise | 5.1 hrs | 3.8 hrs |
This makes it easier to find specific weaknesses.
For example:
Cloud incidents consistently take longer
may indicate:
- insufficient cloud telemetry;
- weak detection rules;
- complicated containment authority.
Segment Metrics by Detection Source
Useful categories include:
- EDR;
- SIEM;
- identity;
- cloud-native;
- network;
- user report;
- third party;
- law enforcement.
A SOC may discover that:
EDR incidents are detected quickly
while:
supplier-related incidents are discovered hours later.
That changes where investment should go.
The 2026 Threat Environment Makes Long-Tail Metrics Important
Mandiant’s data demonstrates why average-only SOC reporting can mislead.
The overall global median dwell time was 14 days, but espionage and DPRK IT-worker investigations had a median dwell time of 122 days.
That means a small number of stealthy incident types can behave very differently from the general population.
Your dashboard should therefore segment:
- ransomware;
- identity compromise;
- espionage;
- third-party compromise;
- cloud compromise.
Verizon 2026: Vulnerabilities and Third Parties Deserve Separate Metrics
Verizon’s 2026 DBIR reports that exploitation of vulnerabilities accounted for 31% of breach entry points, while third-party supply-chain involvement reached 48% in its dataset.
That supports tracking additional SOC measures such as:
- vulnerable-asset detection coverage;
- supplier incident notification time;
- externally discovered incidents;
- third-party containment time.
A modern SOC does not operate only inside its own endpoints.
SOC Metrics vs Regulatory Deadlines
This is an important correction to your current article.
Operational metrics such as:
MTTD
MTTA
MTTC
are not themselves regulatory clocks.
They can affect how quickly the organization understands an incident, but legal reporting deadlines depend on their own triggers.
SEC Reporting
For domestic SEC registrants, a material cybersecurity incident generally must be disclosed on Form 8-K Item 1.05 within four business days after the company determines the incident is material. The clock is not automatically tied to detection. The materiality determination must be made without unreasonable delay.
So do not write:
Slow MTTD automatically causes a missed SEC four-day deadline.
A better statement is:
Slow detection can delay the organization’s ability to investigate and assess business impact, which may complicate materiality analysis and disclosure readiness.
For the full workflow, see SEC Cyber Incident Disclosure Checklist.
CIRCIA
Your current article says:
CIRCIA 72-hour notification rules
That wording should be changed.
CISA says organizations are not required to submit CIRCIA cyber-incident or ransom-payment reports until the final rule becomes effective.
CIRCIA’s statutory framework includes:
- 72-hour covered-cyber-incident reporting;
- 24-hour ransom-payment reporting,
once the mandatory regulatory regime becomes effective.
Use:
“future CIRCIA reporting readiness”
rather than:
“current CIRCIA 72-hour compliance.”
For details, see CIRCIA 2026 Reporting Readiness.
UK and Other Reporting Regimes
Likewise, UK GDPR, DORA, NIS2, and other frameworks use their own legal triggers.
MTTD or MTTC may help the organization develop facts more quickly.
They do not replace the legal trigger analysis.
For a comparison, see Cyber Incident Reporting Deadlines: US vs UK.
SOC Metrics Should Support Executives, Not Overwhelm Them
Executives do not need every SOC metric.
They need metrics linked to business risk.
Useful board-level questions include:
- Are Critical incidents detected faster?
- How many major incidents are discovered externally?
- What is our P90 containment time?
- Which environments have the worst visibility?
- Are supplier-related incidents slower?
- Are recovery times improving?
- Is alert fatigue getting worse?
For governance-focused reporting, see Board-Level Cybersecurity Metrics Guide.
Operational Dashboard vs Board Dashboard
SOC Operations Dashboard
Can include:
- MTTD;
- MTTA;
- triage time;
- backlog;
- false positives;
- detection rules;
- containment actions.
Board Dashboard
Should emphasize:
- material incidents;
- Critical MTTD/MTTC trends;
- externally discovered incidents;
- recovery time;
- supplier exposure;
- key control gaps;
- risk trend.
The audiences are different.
Cybersecurity Time SOC KPI Framework
I recommend organizing metrics into five groups.
Detection
- MTTD
- internal discovery rate
- detection coverage
Analyst Operations
- MTTA
- triage time
- backlog age
- false positive rate
Response
- MTTR
- MTTC
- containment decision time
Recovery
- recovery time
- incident closure time
Quality
- recurrence rate
- automation error rate
- missed-detection rate
- post-incident corrective actions
This gives the article considerably more original practical value than a simple list of seven numbers.
Measure Decision Delay Separately
Many SOC bottlenecks are not technical.
Example:
Incident confirmed: 09:00
Containment approved: 09:42
Containment executed: 09:48
The technical action took:
6 minutes
The decision process took:
42 minutes
That is a governance problem.
Measure:
validation → containment decision
and:
decision → technical action
separately when possible.
Measure Vendor Delay Separately
Example:
SOC identifies supplier compromise: 10:00
Internal response decision: 10:15
Vendor acknowledges request: 12:20
Vendor completes containment: 15:30
Your internal SOC may be functioning well.
The supplier relationship is not.
Track:
vendor acknowledgement time
and:
vendor containment time
for critical third parties.
Automation Should Reduce the Right Delays
An automation program should target known bottlenecks.
Examples:
If MTTA is poor:
- improve alert routing;
- priority paging;
- queue management.
If triage is poor:
- automate enrichment;
- asset context;
- identity lookup.
If MTTC is poor:
- automate high-confidence endpoint isolation;
- session revocation;
- malicious indicator blocking.
Do not automate merely to increase the percentage shown on a dashboard.
Common SOC Metrics Mistakes
1. Tracking Only Averages
Use median and percentiles.
2. Combining All Severity Levels
Segment Critical/High/Medium/Low.
3. Treating MTTR as Universally Defined
State whether it means Respond, Recover, Repair, or Remediate.
4. Confusing Dwell Time With MTTD
They overlap but are used differently.
5. Treating Regulatory Deadlines as SOC KPIs
SEC, CIRCIA, UK GDPR and other rules use legal triggers separate from operational metrics.
6. Optimizing False Positives by Suppressing Too Much
Do not improve the metric by creating detection blindness.
7. Measuring Automation Volume Instead of Outcome
Track time saved and quality.
8. Ignoring Long-Tail Incidents
P90/P95 often reveal the real risk.
9. Ignoring Third-Party Delays
Supplier response can dominate total incident time.
10. Reporting Metrics Without Business Context
A metric should help someone make a decision.
SANS guidance similarly emphasizes developing SOC metrics collaboratively so they align with broader organizational objectives rather than being created in isolation.
Example Quarterly SOC Scorecard
| KPI | Q1 | Q2 | Q3 | Direction |
|---|---|---|---|---|
| Median MTTD | 31 min | 24 min | 18 min | Better |
| P90 MTTD | 4.2 hrs | 3.1 hrs | 2.1 hrs | Better |
| MTTA | 9 min | 7 min | 5 min | Better |
| Median triage | 22 min | 17 min | 13 min | Better |
| P90 backlog age | 4.8 hrs | 3.2 hrs | 2.2 hrs | Better |
| Median MTTC | 38 min | 29 min | 21 min | Better |
| False positive rate | 26% | 22% | 19% | Better |
| Internal discovery | 70% | 77% | 81% | Better |
| Recovery time | 11 hrs | 9 hrs | 7.2 hrs | Better |
These figures are illustrative.
The real value is the trend.
A 90-Day SOC Metrics Improvement Plan
Days 1–30: Define
Document:
- MTTD;
- MTTA;
- MTTR;
- MTTC;
- recovery time;
- false-positive criteria.
Decide exact start and stop points.
Days 31–60: Measure
Establish:
- mean;
- median;
- P90;
- severity breakdown;
- incident-type breakdown.
Identify unreliable data.
Days 61–90: Improve
Find the largest bottleneck.
For example:
slow acknowledgement
→ fix staffing/routing.
slow cloud containment
→ improve permissions/playbooks.
high false positives
→ tune detections.
supplier delay
→ update contracts/escalation.
Then measure again.
Frequently Asked Questions
What are the most important SOC efficiency metrics?
A useful core set includes:
- MTTD;
- MTTA;
- triage time;
- backlog age;
- MTTC;
- response time;
- dwell time;
- false positive rate;
- automation outcomes;
- recovery time.
What is a good MTTD?
There is no universal target.
Appropriate values depend on:
- incident type;
- severity;
- environment;
- telemetry;
- business criticality.
For details, see Mean Time to Detect.
What is a good MTTC?
Again, there is no universal benchmark.
Active ransomware and privileged-account compromise may justify far more aggressive internal targets than low-risk events.
Is dwell time the same as MTTD?
No.
Dwell time generally measures attacker presence before discovery.
MTTD is usually an organization’s internally calculated mean detection interval.
Mandiant reported a 14-day global median dwell time in its M-Trends 2026 dataset, but that should not be treated as a universal MTTD benchmark.
What does MTTR mean?
It depends on the organization.
Common meanings include:
- Respond;
- Recover;
- Repair;
- Remediate.
Cybersecurity Time uses Mean Time to Respond and recommends explicitly stating the interval.
Should a SOC track false positive rate?
Yes, but not alone.
A lower false-positive rate is only useful if detection coverage remains strong.
Is automation coverage a good SOC metric?
It can be, but automation outcomes are more useful than raw volume.
Measure:
- time saved;
- containment improvement;
- errors;
- analyst overrides;
- failed automations.
Are SEC reporting deadlines based on MTTD?
No.
The SEC’s Item 1.05 deadline for domestic registrants is generally four business days after the company determines the incident is material.
Is CIRCIA’s 72-hour reporting requirement currently mandatory?
Not yet.
CISA states organizations are not required to submit CIRCIA incident or ransom-payment reports until the final rule takes effect.
Is NIST SP 800-61 Rev. 2 still current?
No.
NIST finalized SP 800-61 Rev. 3 on April 3, 2025, superseding Rev. 2.
Final Takeaway
SOC efficiency should not be reduced to:
how many alerts were closed.
The more useful question is:
How quickly and reliably does the SOC turn meaningful signals into effective defensive outcomes?
A mature measurement chain looks like:
detect → acknowledge → triage → validate → respond → contain → recover
The strongest SOCs measure each transition, distinguish mean from median and long-tail performance, segment results by severity and attack type, and investigate the bottlenecks that create the largest business risk.
Current threat research reinforces why this matters.
Mandiant’s 2026 data shows both long-lived attacker dwell time and extremely rapid adversary hand-offs, while Verizon’s 2026 DBIR highlights increased vulnerability exploitation and third-party involvement.
At the same time, NIST’s current incident-response guidance emphasizes organization-wide detection, response, and recovery rather than treating incident handling as an isolated SOC activity.
So the right executive question is not:
“Is our SOC efficient?”
It is:
“Where are we losing time between detection and recovery, and does that delay materially increase our risk?”
That is what a good SOC metrics program should reveal.
Recommended Links
MTTD vs MTTR vs MTTC vs Dwell Time
Average Time to Detect Cyber Attack
Cybersecurity Incident Response Timeline
Board-Level Cybersecurity Metrics Guide
I recommend 6–7 contextual internal links.